
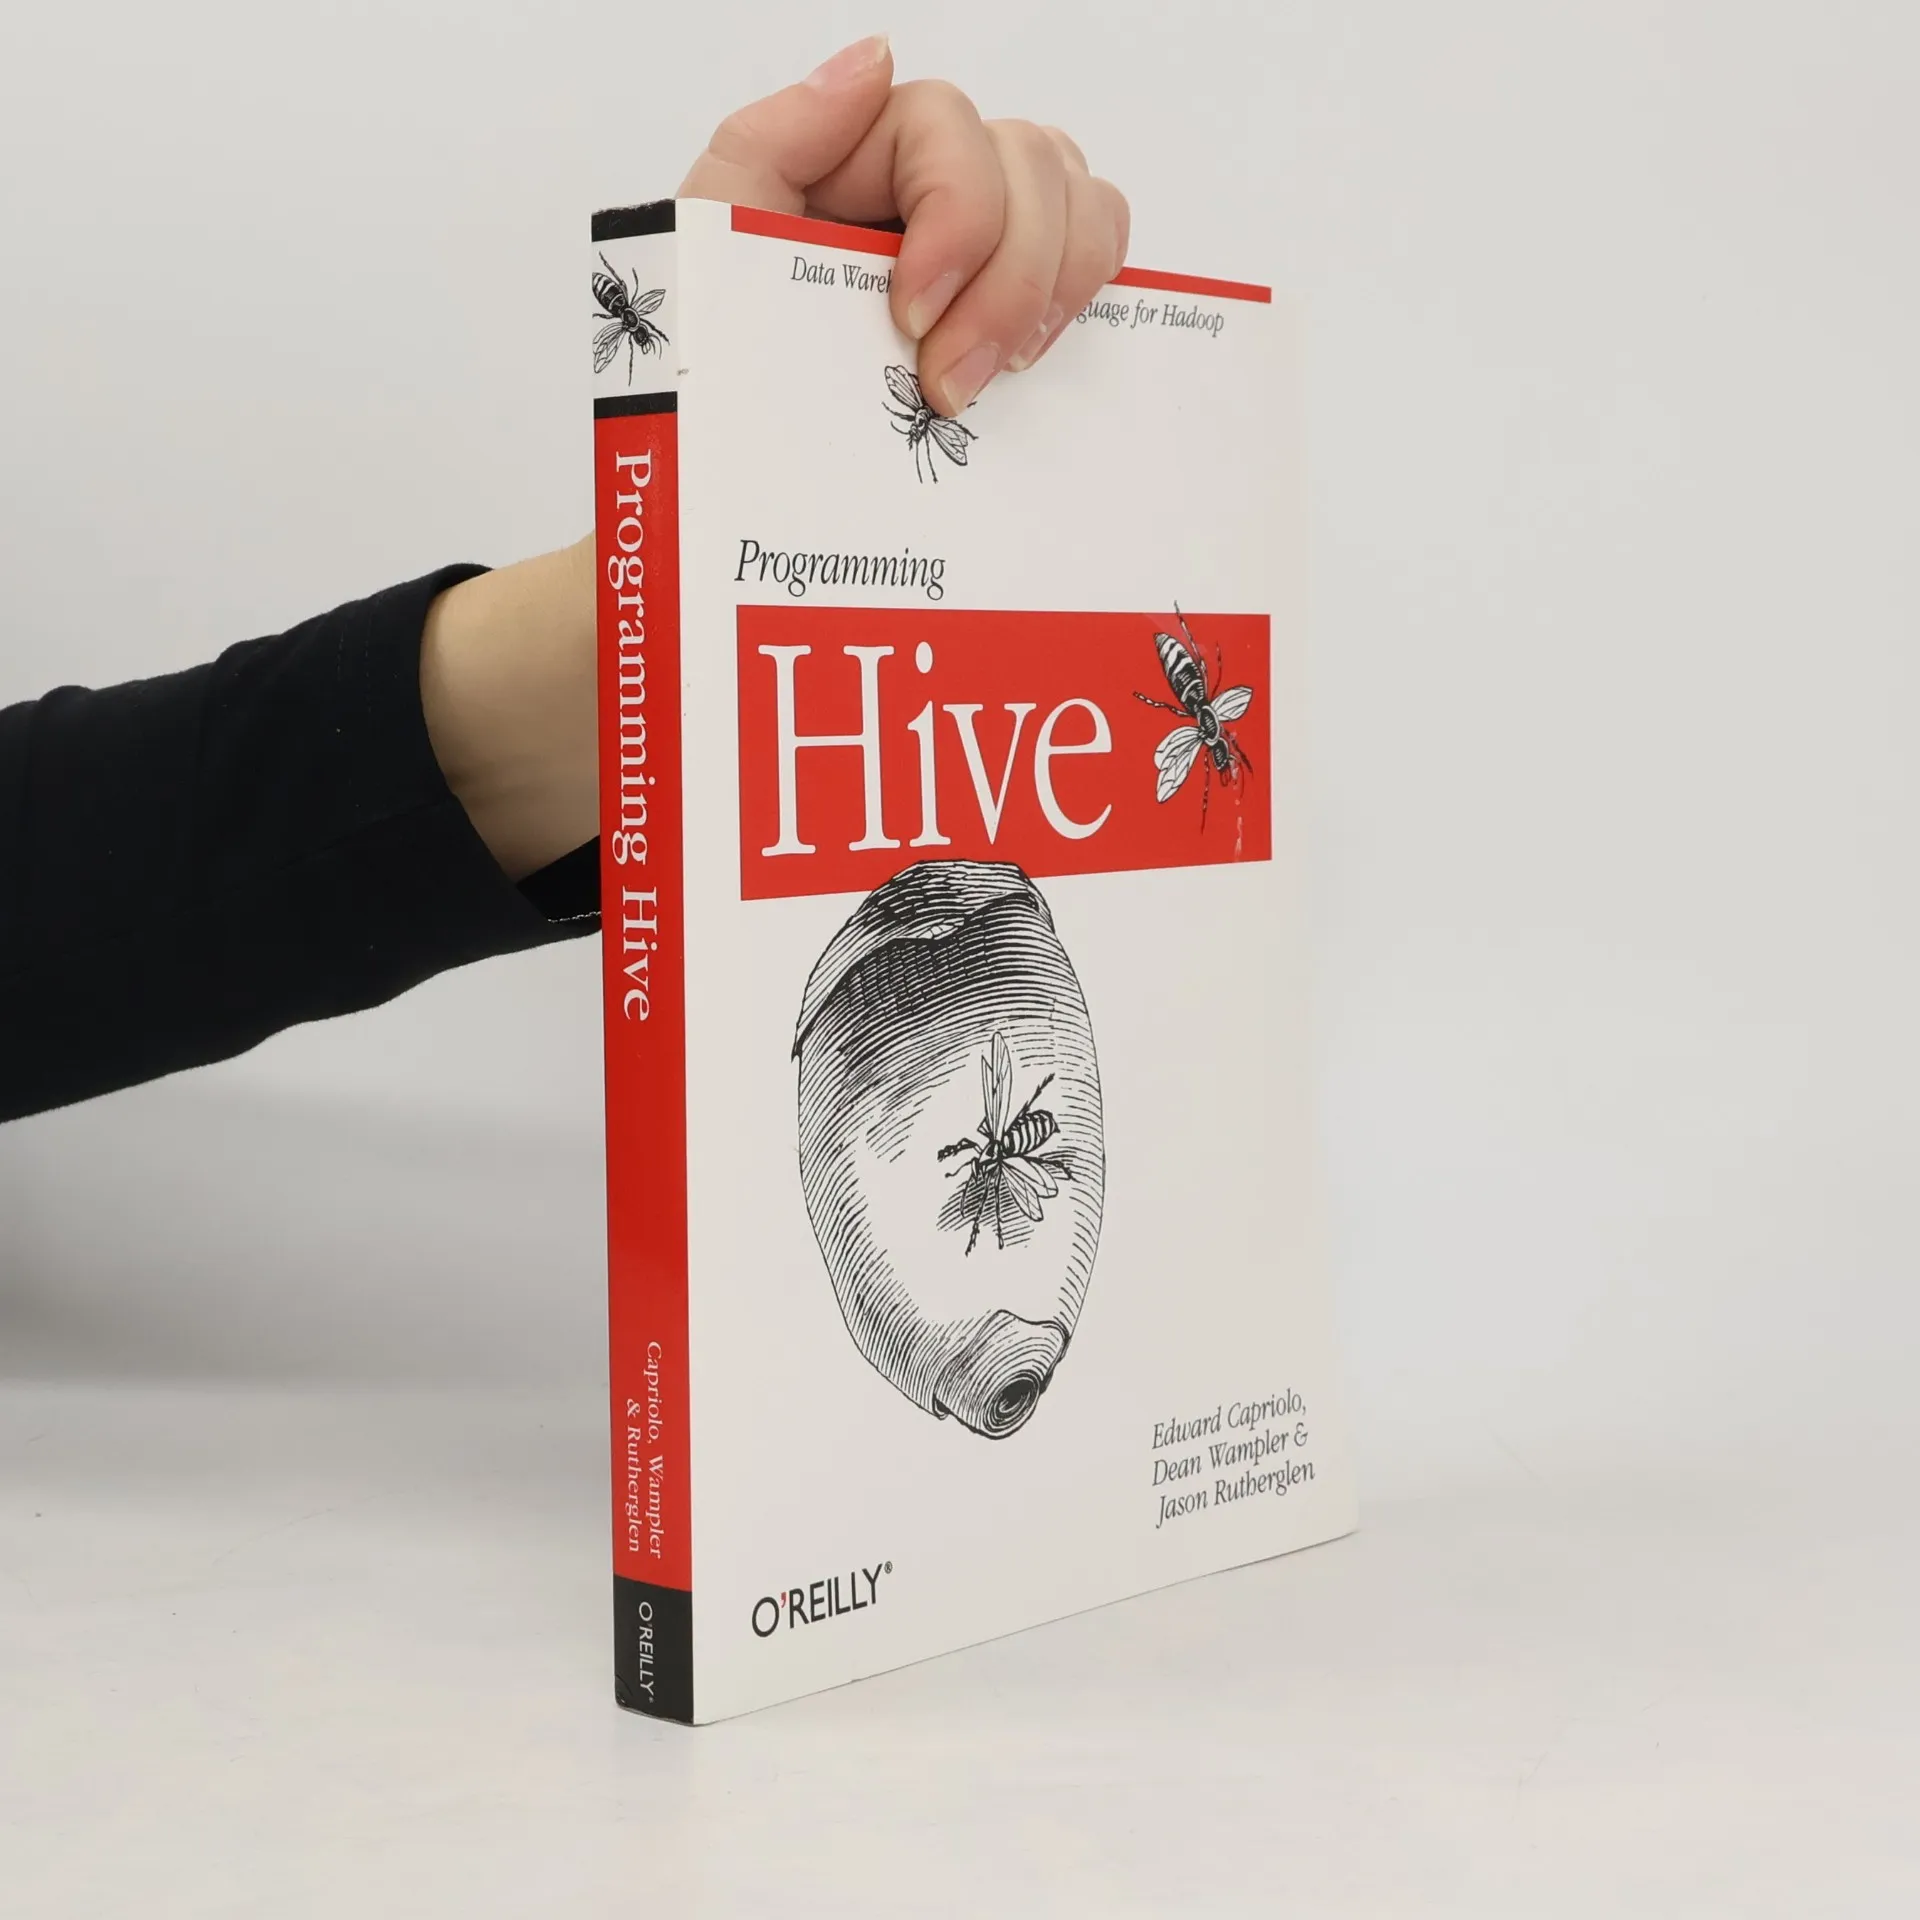
Programming Hive
Data Warehouse and Query Language for Hadoop
Viac o knihe
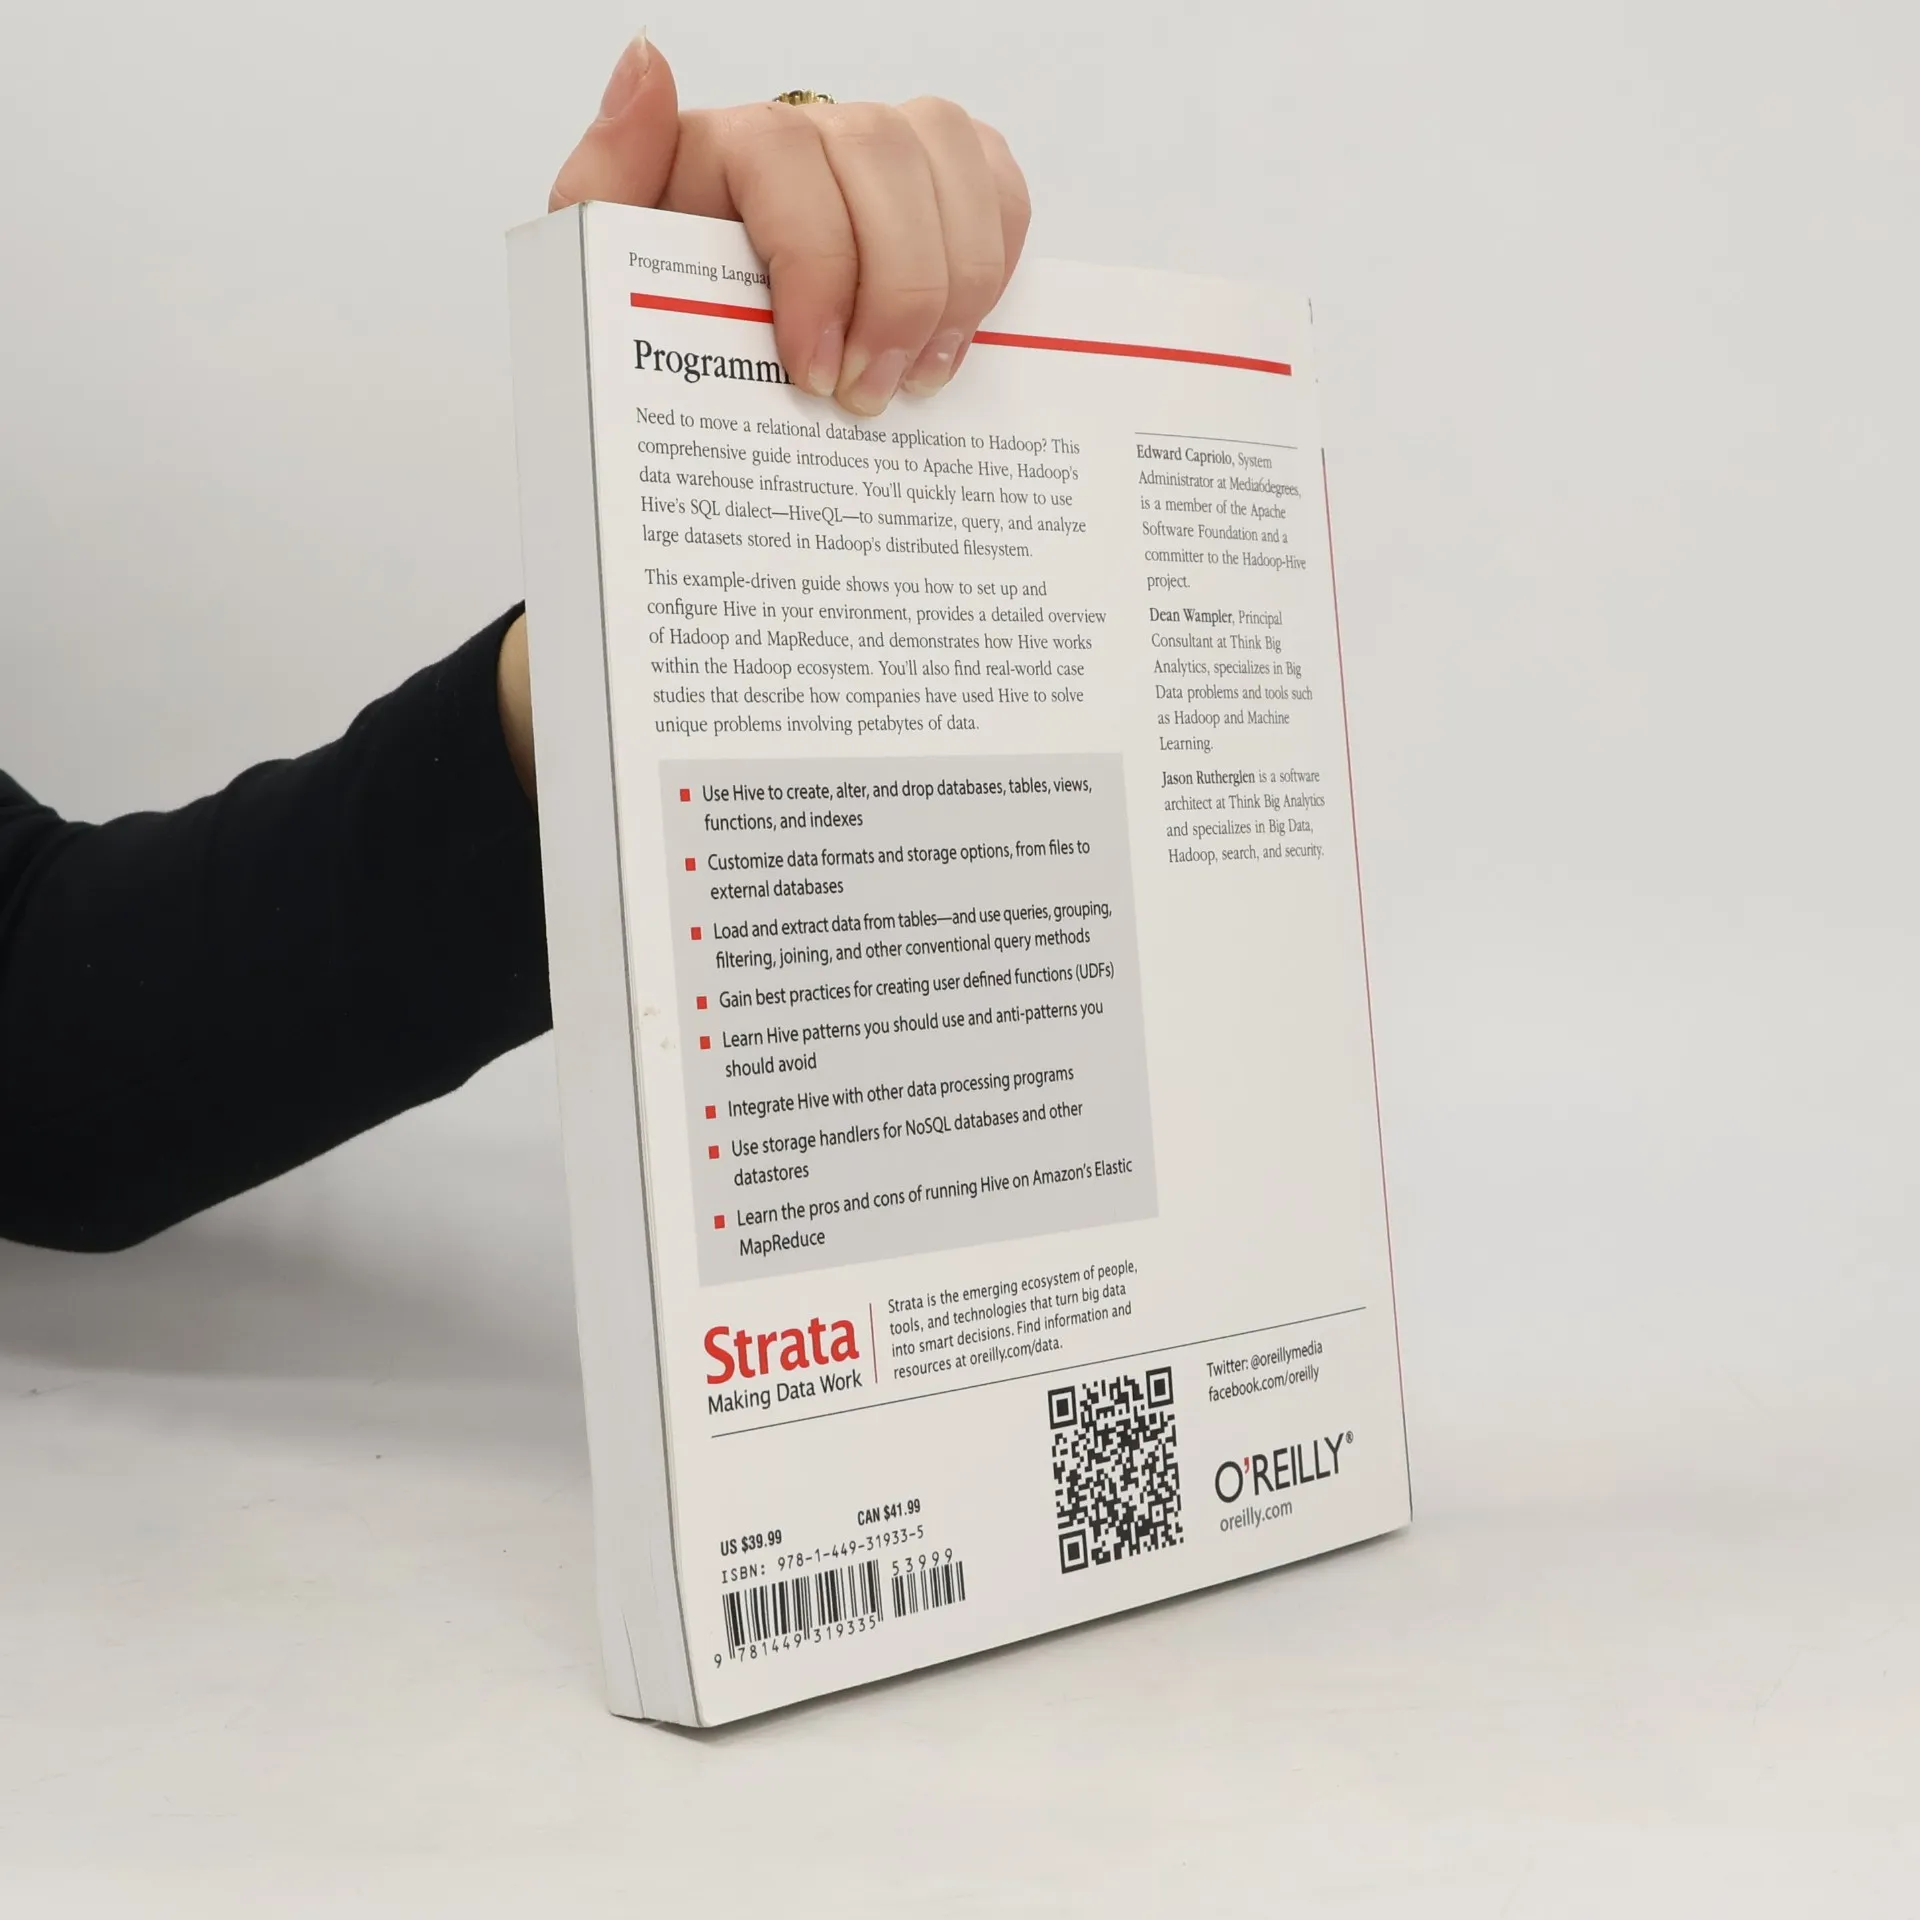
Need to move a relational database application to Hadoop? This comprehensive guide introduces you to Apache Hive, Hadoop’s data warehouse infrastructure. You’ll quickly learn how to use Hive’s SQL dialect—HiveQL—to summarize, query, and analyze large datasets stored in Hadoop’s distributed filesystem. This example-driven guide shows you how to set up and configure Hive in your environment, provides a detailed overview of Hadoop and MapReduce, and demonstrates how Hive works within the Hadoop ecosystem. You’ll also find real-world case studies that describe how companies have used Hive to solve unique problems involving petabytes of data. Use Hive to create, alter, and drop databases, tables, views, functions, and indexes Customize data formats and storage options, from files to external databases Load and extract data from tables—and use queries, grouping, filtering, joining, and other conventional query methods Gain best practices for creating user defined functions (UDFs) Learn Hive patterns you should use and anti-patterns you should avoid Integrate Hive with other data processing programs Use storage handlers for NoSQL databases and other datastores Learn the pros and cons of running Hive on Amazon’s Elastic MapReduce
Nákup knihy
Programming Hive, Dean Wampler, Jason Rutberglen, Edward Capriolo
- Jazyk

- Rok vydania
- 2012
- Väzba
- (mäkká),
- Stav knihy
- Poškodená
- Cena
- 10,49 €
Doručenie
Platobné metódy
Nikto zatiaľ neohodnotil.
- Titul
- Programming Hive
- Podtitul
- Data Warehouse and Query Language for Hadoop
- Jazyk
- anglicky
- Vydavateľ
- O'Reilly Media
- Rok vydania
- 2012
- Väzba
- mäkká
- Počet strán
- 347
- ISBN10
- 1449319335
- ISBN13
- 9781449319335
- Série
- Anotácia
- Need to move a relational database application to Hadoop? This comprehensive guide introduces you to Apache Hive, Hadoop’s data warehouse infrastructure. You’ll quickly learn how to use Hive’s SQL dialect—HiveQL—to summarize, query, and analyze large datasets stored in Hadoop’s distributed filesystem. This example-driven guide shows you how to set up and configure Hive in your environment, provides a detailed overview of Hadoop and MapReduce, and demonstrates how Hive works within the Hadoop ecosystem. You’ll also find real-world case studies that describe how companies have used Hive to solve unique problems involving petabytes of data. Use Hive to create, alter, and drop databases, tables, views, functions, and indexes Customize data formats and storage options, from files to external databases Load and extract data from tables—and use queries, grouping, filtering, joining, and other conventional query methods Gain best practices for creating user defined functions (UDFs) Learn Hive patterns you should use and anti-patterns you should avoid Integrate Hive with other data processing programs Use storage handlers for NoSQL databases and other datastores Learn the pros and cons of running Hive on Amazon’s Elastic MapReduce